Oct 14, 2026
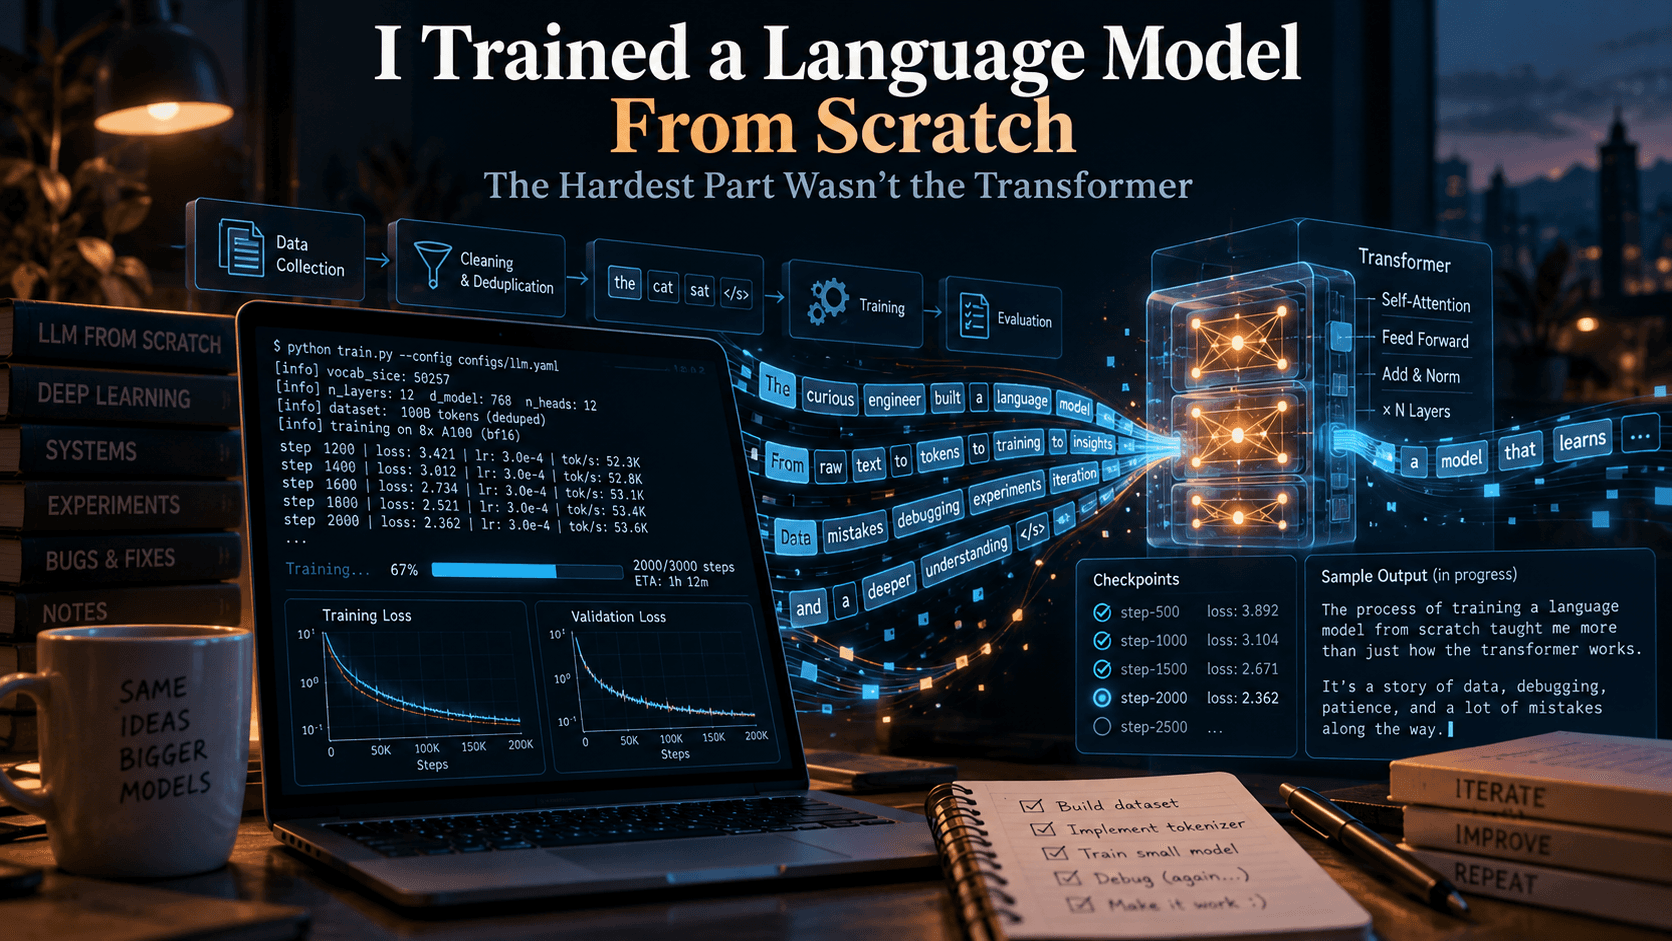
I Trained a Language Model From Scratch. The Hardest Part Wasn't the Transformer.
Personaltech
Building a Transformer was the fun part. Preparing nearly a billion tokens of training data, debugging pipelines, managing GPU time, and figuring out whether the model was actually learning turned out to be much harder. I trained two small language models from scratch, starting at 29.9M parameters and scaling to 60.1M. Here's what I learned along the way, including the mistakes, unexpected challenges, and why understanding the process was more valuable than the final model.
Read article